This article defines semantic content architecture as organizing content around entities, typed relationships, and machine-readable markup. It distinguishes it from topic clusters, information architecture, and schema markup, details four relationship types—hierarchical, sequential, contrastive, dependency—and lays out a build sequence from entity inventory to bidirectional linking and JSON-LD. It closes with common legibility failures and maintenance habits for scaling.
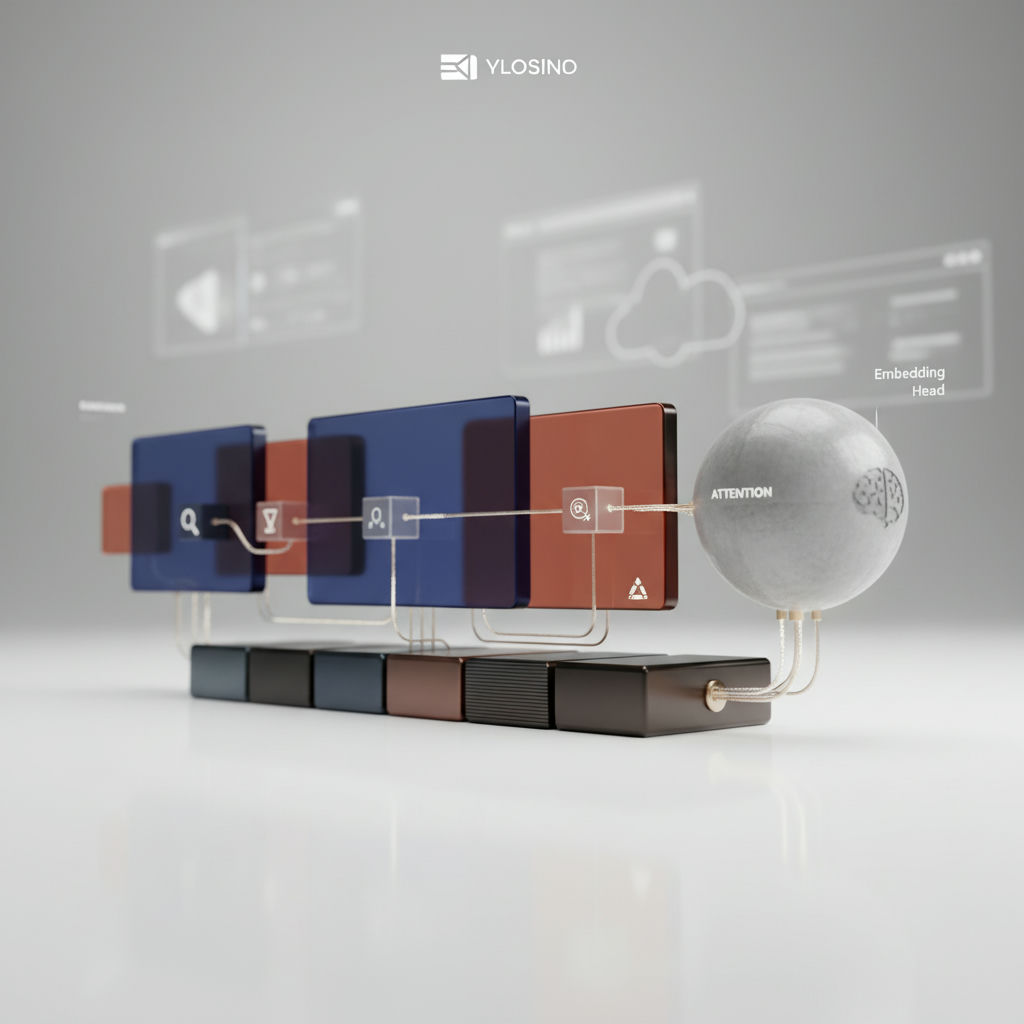
Semantic content architecture is the practice of organizing content, internal links, and metadata around entities and their explicit relationships rather than isolated keywords or page hierarchies alone. It structures information around entities and their attributes and relationships rather than keyword frequency, the same foundation Enterprise Knowledge describes for ontologies, which define the types of things that exist in a domain and the properties used to describe them.
The mistake most teams make is treating semantic content architecture as upgraded internal linking or smarter keyword grouping. Good writing alone does not create that structure. A well-written page can clarify one topic, but architecture defines what the subjects are across the entire site, how they connect, and how machines can read those connections consistently.
That requires four distinct pillars working together: entities or concepts as canonical subjects, explicit relationships typed between them, machine-readable markup that exposes those relationships, and topical clustering that groups related pages around a concept instead of scattering them in a navigation hierarchy.
Most published guides stop at the abstract definition. They name entities and relationships but never show a worked entity map, relationship types, or markup pattern you can actually apply, which is why implementations collapse into generic clusters.
That framing only holds up if the term is cleanly separated from the concepts readers most often confuse it with.
Semantic content architecture is not interchangeable with topic clusters, information architecture, or schema markup. Each solves one layer of legibility, while semantic content architecture is the full stack that ties entities, relationships, and machine-readable labels together.
The sharpest boundary is the topic-cluster model itself. HubSpot's definition, popularized in its pillar-cluster work, describes topic clusters as an organized network where a broad pillar links to focused cluster pages and each cluster links back to the pillar. With the boundaries between these terms fixed, the next question is how the relationships between entities actually get built.
Topic clusters organize published pages into topical neighborhoods to signal depth to both readers and crawlers. The pillar owns the head term and breadth; clusters own long-tail subtopics and depth. What they organize: articles by subject affinity. Primary unit: pillar page and cluster page. What they're missing alone: no typed relationship vocabulary (is-a, part-of, requires), no machine-readable layer, and no navigation taxonomy beyond hub-and-spoke internal links. Relation to semantic content architecture: topic clusters are the clustering layer, necessary for topical authority but not sufficient to make entity relationships explicit.
Information architecture organizes site content and functionality for human wayfinding. Nielsen Norman Group frames IA as the underlying organization, structure and nomenclature distinct from visible navigation, validated through methods like card sorting and tree testing. What it organizes: functionality and information into findable taxonomies, labels, and navigation paths. Primary unit: category, label, and navigational hierarchy. What it's missing alone: entity semantics within article copy, content depth signals, and machine-readable expression of meaning. Relation to semantic content architecture: IA provides the navigational skeleton; semantic content architecture enriches that skeleton with explicit entity relationships and internal linking that reflects meaning, not just location.
Schema markup organizes meaning for crawlers using shared vocabularies like Schema.org expressed as JSON-LD. Google's documentation notes that for a link to be reliably crawlable it should be a standard HTML anchor with an href attribute, the same crawl layer structured data depends on. What it organizes: page-level facts into types and properties (Article, FAQPage, Product, author, date). Primary unit: type/property statement. What it's missing alone: content strategy, topical depth, and linking logic; valid markup on isolated pages does not create authority or relationship context. Relation to semantic content architecture: schema markup is the machine-readable expression layer; semantic content architecture defines what should be marked up and how those entities connect.
| Concept | What it organizes | Primary unit | What it's missing alone | How it relates to semantic content architecture |
|---|---|---|---|---|
| Semantic Content Architecture | Entities, typed relationships, structured data, topical neighborhoods | Entity + relationship type | Governance required; not automatic from templates | Full stack integrating the other three layers |
| Topic Clusters | Content into topical authority neighborhoods | Pillar page + cluster page | Typed relationships, machine markup, navigation taxonomy | Clustering layer of semantic content architecture |
| Information Architecture | Findable taxonomies and navigation | Category / label / navigation path | Entity semantics, content depth, machine layer | Navigational skeleton semantic architecture enriches |
| Schema Markup | Page meaning for crawlers via shared vocabularies | Schema.org type / property (JSON-LD) | Content strategy, linking logic, topical depth | Machine-readable expression layer of semantic architecture |
Schema markup alone or a topic-cluster template alone is not semantic content architecture. Each solves only one layer of the problem.
Entity relationships in semantic content architecture break into four typed links, hierarchical (is-a/part-of), sequential (step order), contrastive (difference/alternative), and dependency (prerequisite), and each dictates a specific internal-linking pattern.
You face this choice every time you publish: does the new guide on "churn analysis" belong under "retention metrics" as a child, after "cohort setup" as the next step, alongside "NPS vs. CSAT" as an alternative, or only after "data instrumentation" as a prerequisite.
Hierarchical (is-a / part-of). This is the taxonomy backbone that ontology practice is built on. Enterprise Knowledge defines an ontology as a model that organizes structured and unstructured information through entities, their properties, and the way they relate to one another, with a relationship as a link between objects in the ontology. A class hierarchy includes a class and sub classes organized hierarchically, where a subclass inherits the attributes and relationships of the parent class. W3C codifies this with rdfs:subClassOf for is-a axioms. Linking pattern: parent pillar links down to all children with descriptive anchors, each child links back up to the parent, plus breadcrumb markup. Keep inheritance strict. If a child does not inherit most attributes, make it a separate class with an associative link instead.
Sequential. Step-order links where order matters. This is not hierarchical, it is workflow. Linking pattern: a numbered hub page that links forward in order, and each subpage carries explicit prev/next navigation with process anchor text such as "after you define cohorts, build the churn definition" and a progress tracker.
Contrastive. Entities that are alternatives or mutually exclusive, formalized in OWL via owl:disjointWith. Linking pattern: dedicated comparison pages, reciprocal cross-links between alternatives, and inline callouts that state the difference. A "Header Bidding vs Open Bidding" page should link both ways to the individual concept pages, not sit in isolation.
Dependency. A knowledge prerequisite that is neither a parent nor a next step. Example: you cannot reason about LTV without defining retention. Linking pattern: prerequisite box at the top of the dependent article, required-reading links before the how-to, and unidirectional links from dependent to prerequisite. The prerequisite does not need to link back.
Knowing which relationship types apply is only useful once they're assembled into an actual build sequence.
Building semantic content architecture means turning an entity inventory into dedicated concept pages, bidirectional internal links, and JSON-LD markup that Google lists as its recommended format for helping systems understand what a page means. The tension it resolves is a clean conceptual map that humans understand versus concrete page-level signals that machines can actually extract.
HarperFlow publishes highly structured articles featuring FAQs, data tables, and direct-answer blocks that meet the rigorous citation standards required by AI search engines. By continuously auditing and improving your content through AI answer analytics, HarperFlow helps your site build long-term authority and visibility that outlasts ad-dependent strategies.
Start with an audit of what you already publish, extract the recurring entities (people, products, processes), and cluster them by shared intent. Each cluster becomes a pillar defined by a single, stable canonical topic, not a keyword variant. Prioritize on evidence of demand and internal expertise, not volume.
Give every pillar its own destination page that owns the definition, scope, and boundary of that entity. Supporting articles should not re-define the pillar; they extend it. That prevents duplication and gives internal linking a clear hub to point to.
Implement links in both directions between the pillar page and its children, and laterally between related concepts where the relationship types above call for it. Use descriptive anchor text that states the relation, keep navigation consistent, and ensure every concept page has inbound links from relevant content. If a page has no inbound path, crawlers treat it as orphaned.
Translate each page's meaning into Schema.org vocabulary using JSON-LD in a script block, which Google documents as supporting explicit clues about the meaning of a page and using that data to understand people, books, companies and other entities. Place the markup on the page it describes, use the most specific applicable type, and ensure content in structured data matches what readers see on the page. Validate with Rich Results Test and URL Inspection during development, then monitor coverage after deploy. When markup, copy, and links all express the same relationships, passage extractors have three aligned signals for the same entity instead of one fragile hierarchy.
Structural mistakes that break machine legibility cause parsers to ignore even well-modeled entities, most commonly when concept pages have zero inbound internal links, anchors optimize for keywords instead of entity relationships, and JSON-LD is missing or invalid.
Ahrefs flags "Orphan page" errors when URLs have no incoming internal links in its Site Audit, because crawlers relying on link architecture never discover them. Visitors can't navigate to them either, and link equity does not flow.
The failure modes to audit after you build:
Run two checks on every publish: a crawl for orphans and a structured-data validation in Rich Results Test and Schema Markup Validator. Log fixes in your content ops checklist, not as one-off patches.
An architecture with perfect entity mapping but broken or missing structured data is functionally invisible to machine parsers.
Getting the structure right by hand is possible. The real constraint is sustaining it at publishing scale.
Semantic content architecture stays intact only when every new article is wired into your existing entity graph with consistent structured data; otherwise the library grows but legibility shrinks. It is a maintenance habit, not a one-time build. When new posts point to unrelated trending topics instead of their parent concepts, or ship without markup, you create islands that machines cannot connect.
Before you ship, pressure-test your process:
If your team cannot answer yes without a manual scramble, the workflow, not the model, is the gap. Some teams solve that by embedding the checks into publishing itself: automated Webflow publishing tools can build entity linking and structured data into each article by default, which is one way to keep the discipline consistent without separate audits.
The teams that win publish less at random and maintain the graph every time they publish.
If the new topic inherits most attributes and relationships of a parent, model it as a subclass and build it as a child of that pillar. If it has distinct properties and does not inherit, create a separate canonical entity and connect it with an associative link instead of forcing hierarchy. Track the decision in a single glossary so naming stays consistent.
Is-a uses subclass inheritance defined by rdfs:subClassOf, where a child inherits parent attributes, so link parent down to all children and each child back up with breadcrumbs. Part-of is composition where the child is a component but does not share all attributes, so use part-of phrasing and avoid assuming full inheritance.
Use contrastive modeling when two entities are alternatives or mutually exclusive, which OWL expresses with owl:disjointWith. Build a dedicated comparison hub plus reciprocal cross-links between the individual concept pages and inline callouts that state the difference. That signals alternative status rather than a parent-child relation.
Create a hub page that orders steps explicitly and give each step prev/next navigation with process anchors such as "after you define cohorts". Keep sequential links separate from hierarchical pillar links so workflow order is not confused with taxonomy depth.
Ahrefs defines orphan pages as URLs with no incoming internal links. Fix them by adding contextual links from related clusters and ensuring every link uses a standard HTML anchor with href so crawlers can follow the new paths.
Replace generic exact-match anchors with sentences that declare the relation, for example "churn analysis is a type of retention metric" for hierarchical or "requires instrumentation first" for dependency. This helps parsers distinguish is-a, part-of, alternative, and prerequisite links instead of seeing repeated keyword links.
Place structured data on the page it describes and do not mark up content that is not visible to readers. Google lists JSON-LD as recommended and advises starting with the Rich Results Test and the Schema Markup Validator for generic checks.
No. Two URLs defining the same entity with different names create competing canonicals and force parsers to guess the primary entity. Choose one canonical URL and ID, align title, internal links, and JSON-LD to it, and consolidate thin duplicates into distinct child pages.
Related articles
HarperFlow publishes highly structured articles featuring FAQs, data tables, and direct-answer blocks that meet the rigorous citation standards required by AI search engines. By continuously auditing and improving your content through AI answer analytics, HarperFlow helps your site build long-term authority and visibility that outlasts ad-dependent strategies.
Start Your Trial TodayLover of all things automation and all things content.
Your privacy
Necessary storage keeps the site secure and working. With permission, analytics helps us improve it and marketing tools measure campaigns. Google can still send limited cookieless signals when optional storage is off. Read our Privacy Policy.
Your browser sends a privacy signal (Global Privacy Control), so optional technologies start off — your choice here takes precedence.
Privacy choices
Necessary storage supports security, consent, and the features you request. Optional categories can be changed at any time.
Security, fraud prevention, consent preferences, form delivery, and popup suppression.
Your browser sends a Global Privacy Control signal, so optional technologies start off by default. Your explicit choice here takes precedence.
A practical AEO/GEO manual for making your Webflow site clearer, better sourced, and easier for answer engines to use—without gimmicks or guarantees.
Find gaps in discovery, extraction, evidence, authority, and freshness
Use evidence patterns, briefs, and fill-in worksheets
Run a focused 30-day AEO/GEO operating sprint
We’ve emailed your copy. It should arrive within a few minutes.
If it is not in your inbox within a few minutes, check spam or promotions.